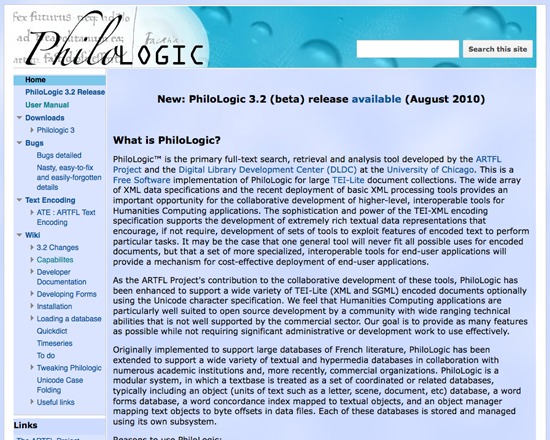
Philologic is a free, open source full-text search, retrieval and analysis tool developed by the ARTFL Project and the Digital Library Development Centre, at the University of Chicago. This tool supports a wide variety of XML and SGML encoded documents, in addition to plain text, Dublin Core and HTML, and includes a MySQL back end. It is designed ot be light, fast and robust, boasts extensive use and testing, and can be used directly 'out of the box' with numerous configuration options built in.
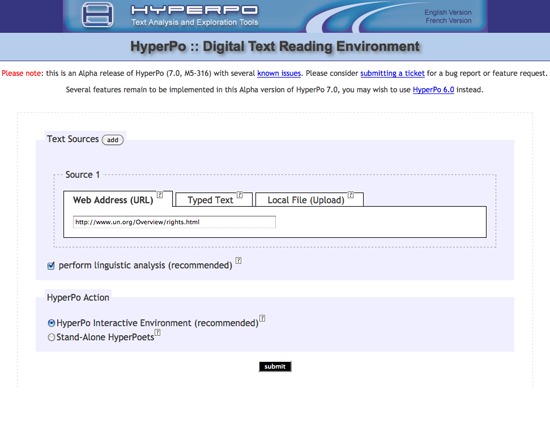
HyperPo is an important legacy tool, developed as the first web-based text analysis tool aimed at humanities scholars available from 1996 through 2006. Users could input a web address, upload a file or directly enter text for analysis. HyperPo's interface was available in both English and French. Though no longer available for use, a capture of HyperPo can be viewed through the Internet Archive's Wayback Machine.
TextGrid is a virtual research environment for text-based humanities scholarship. It offers a variety of tools and services for collaboratively creating, analyzing, editing and publishing texts. The TextGrid environment is split into two components, the Laboratory housing the tools and services, and the Repository for preserving reserach data and making it available to other scholars.
HEURIST (http://HeuristNetwork.org) is an extremely flexible, end-user oriented, web-based data management system designed specifically for Humanities data. Developed since 2005, it has been in active use across many projects since 2009. It is available both as a free web service for researchers (hosted at the University of Sydney Data Centre) or for installation on a physical or virtual server (Open Source on gitHub).
Researchers can design, create, manage, analyse, visualise and publish their own richly-structured database(s) through a simple web interface, without the need for programmer(s). Quite complex databases can be built in a few hours by borrowing structures and vocabularies published by other users. Databases can be designed and built incrementally, as existing data are not affected by changes in structure. Databases created by Heurist are stored in MySQL with a repeatable structure facilitating sustainability and independent access by other software.
Advanced features include record linking, graph structure, drill-down facet searches, rule-based queries, custom reports, linked map-timelines, network visualisation, normalised spreadsheet import, crosstabulation, XML feeds, XSLT transforms. The team provides initial email and skype assistance for project setup at no cost, and special customisations at modest cost.
Heurist is applicable in many domains including History, Archaeology, Anthropology, Cultural Research, Linguistics, Media Studies etc. It handles everything from text, tags and categories, through networks of rich relationships and offset annotations, to images, video, spatial data and dating (including non-western systems and dating uncertainty).
Sophisticated searches (including faceted and rule-based) can be saved, organised and rendered as layered interactive maps, timelines, network visualisations, crosstabulations, lists, custom reports, XML and XSLT transforms, all of which can easily be printed or embedded (live) in a website - Heurist provides the html code required to embed results in a web page or CMS.
Databases can easily be migrated later to a personal or institutional server. Since the data are stored in a standard MySQL database with a fixed and well-documented structure, the data can be accessed directly via SQL from most programming languages independently of Heurist.
Version 4.2 (Jan 2016 onwards) is available as a service via the Heurist website. Version 4 delivers a user-customisable interface of widgets, along with better mapping and visualisation. Existing version 3 databases are bidirectionally compatible with version 4.
Gathers smart search results based on user feedback. Similar to Google Alerts but you can give a thumbs up/down to improve the search results.
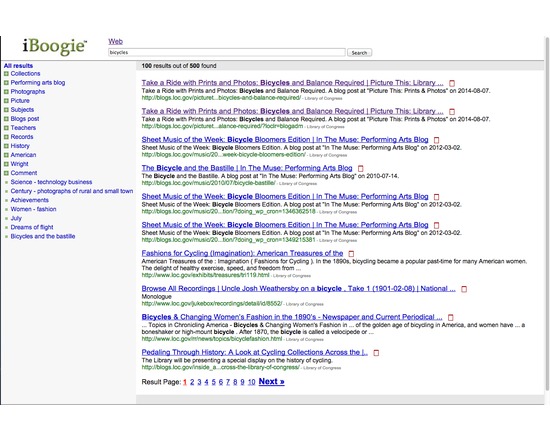
iBoogie is a clustering search engine that puts documents with similar content or with related topics into the same group. Each group is assigned a label based on the content of the documents. The results are presented to the user in a hierarchy of topics (clusters) for browsing.
SearchTeam is a collaborative search engine that allows individuals and groups to curate search results in a public or shared SearchSpace.
Google Scholar searches books and scholarly articles (and optionally patents, legal opinions, and legal journals).
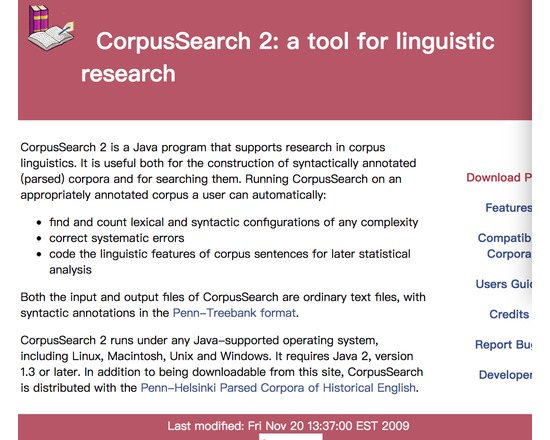
CorpusSearch 2 allows users to construct and search syntactically annotated corpora, including finding and counting lexical and syntactic patterns, correcting systemic errors, and coding linguistic features.
The software is released under Mozilla Public License 1.1 (MPL 1.1) .
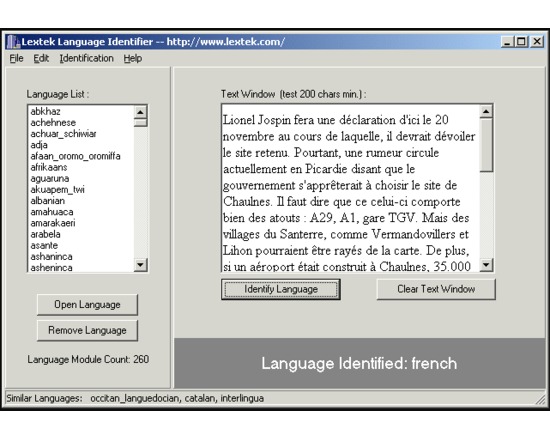
Lextek offers a range of services and software for full-text indexing search and retrieval; automatic classification, routing, and filtering electronic text according to user defined profiles. Lextek also has other stand alone programs which have various functions, among which are: Onix Text Indexing and Retrieval Toolkit; Lextek Profiling Engine; RouteX Document Classifier; Brevity Document Summarizer; Lextek Language Identifier; PhonMatch Phonetic Toolkit