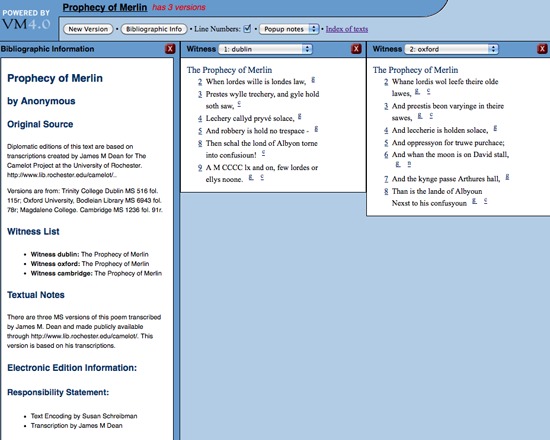
The Versioning Machine, now in version 4.0, is a framework and an interface for displaying multiple versions of text, and encodes the text according to TEI guidelines. It incorporates features found in both critical editions and electronic publication, in addition to providing an environment for textual editors to comparatively view the results of their edits. This tool may be downloaded for use on a local machine, or hosted on one's server for web usage.
Apache Xalan is a free XSLT processor for transforming XML documents into HTML, text or other XML document types, offered by the Apache Software Foundation. This tool uses the Xerces XML parser to converty XML into internal nodesets, and is offered as both C++ and Java implementations.
Abbot is a free tool for converting multiple XML texts with multiple markup schema into a common interoperable file, offered by the MONK (Metadata Offer New Knowledge) Project. It can also read an XML schema file and output procedures, and use them to convert other files into valid XML in alignment with the target schema. While Abbot focusses on TEI, it has been designed to flexibly accomodate other standards and can transform texts into any XML schema required.
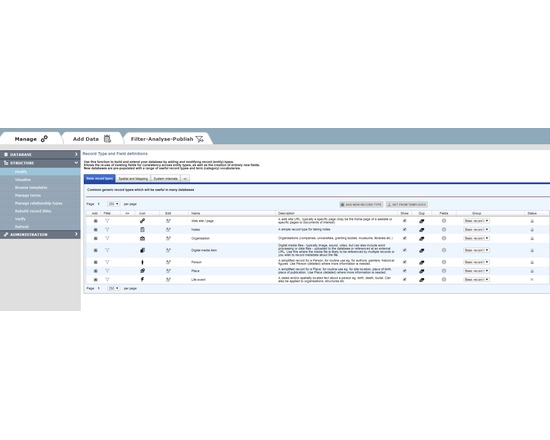
HEURIST (http://HeuristNetwork.org) is an extremely flexible, end-user oriented, web-based data management system designed specifically for Humanities data. Developed since 2005, it has been in active use across many projects since 2009. It is available both as a free web service for researchers (hosted at the University of Sydney Data Centre) or for installation on a physical or virtual server (Open Source on gitHub).
Researchers can design, create, manage, analyse, visualise and publish their own richly-structured database(s) through a simple web interface, without the need for programmer(s). Quite complex databases can be built in a few hours by borrowing structures and vocabularies published by other users. Databases can be designed and built incrementally, as existing data are not affected by changes in structure. Databases created by Heurist are stored in MySQL with a repeatable structure facilitating sustainability and independent access by other software.
Advanced features include record linking, graph structure, drill-down facet searches, rule-based queries, custom reports, linked map-timelines, network visualisation, normalised spreadsheet import, crosstabulation, XML feeds, XSLT transforms. The team provides initial email and skype assistance for project setup at no cost, and special customisations at modest cost.
Heurist is applicable in many domains including History, Archaeology, Anthropology, Cultural Research, Linguistics, Media Studies etc. It handles everything from text, tags and categories, through networks of rich relationships and offset annotations, to images, video, spatial data and dating (including non-western systems and dating uncertainty).
Sophisticated searches (including faceted and rule-based) can be saved, organised and rendered as layered interactive maps, timelines, network visualisations, crosstabulations, lists, custom reports, XML and XSLT transforms, all of which can easily be printed or embedded (live) in a website - Heurist provides the html code required to embed results in a web page or CMS.
Databases can easily be migrated later to a personal or institutional server. Since the data are stored in a standard MySQL database with a fixed and well-documented structure, the data can be accessed directly via SQL from most programming languages independently of Heurist.
Version 4.2 (Jan 2016 onwards) is available as a service via the Heurist website. Version 4 delivers a user-customisable interface of widgets, along with better mapping and visualisation. Existing version 3 databases are bidirectionally compatible with version 4.
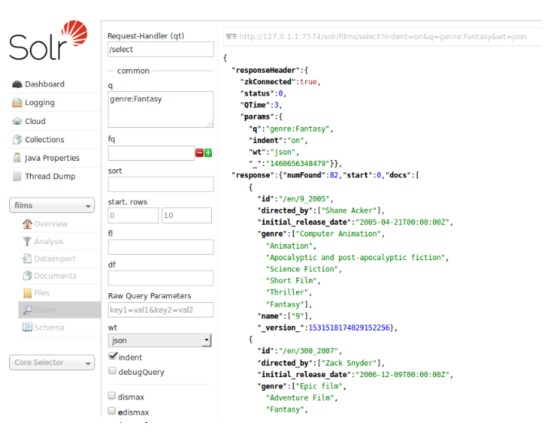
Solr is an open source enterprise search platform from the Apache Lucene project. It operates as a standalone full-text search server within an appropriate servlet container, such as Tomcat. Solr uses the Lucene Java search library at its core for full-text indexing and search, and has REST-like HTTP/XML and JSON APIs that make it easy to use from virtually any programming language.